The defining pattern in this week's chip news is not one company's product launch but a structural shift: the major players are no longer competing only on silicon performance. They are competing to own the surrounding stack - the rack designs, the networking, the software, and increasingly the inference layer where AI actually runs. Microsoft's third-generation Maia chip, Nvidia's open rack contributions, and even the rhetorical rebranding of AI all point in the same direction.
Microsoft Moves Inference In-House
The Verge reports that Microsoft is announcing its third-generation Maia in-house AI chip today, positioning Maia 300 as the "primary AI inference system" for Microsoft's products and services. That phrasing is the tell. Inference - running trained models to serve users - is the volume business in AI, the part that scales with every query, agent action, and reasoning step. Owning that layer reduces reliance on Nvidia's GPUs and gives Microsoft control over cost and efficiency in its cloud.
The Verge also notes Maia 300 is better suited to the latest reasoning models and agentic tasks. That matters because reasoning and agentic workloads are more compute-hungry per interaction than simple chat, and they are becoming the default way AI is consumed. If Microsoft can serve those workloads on its own silicon, it captures margin that would otherwise flow to a merchant chip supplier. The announcement is less a product story than a vertical-integration story.
Nvidia's Answer Is the Open Rack
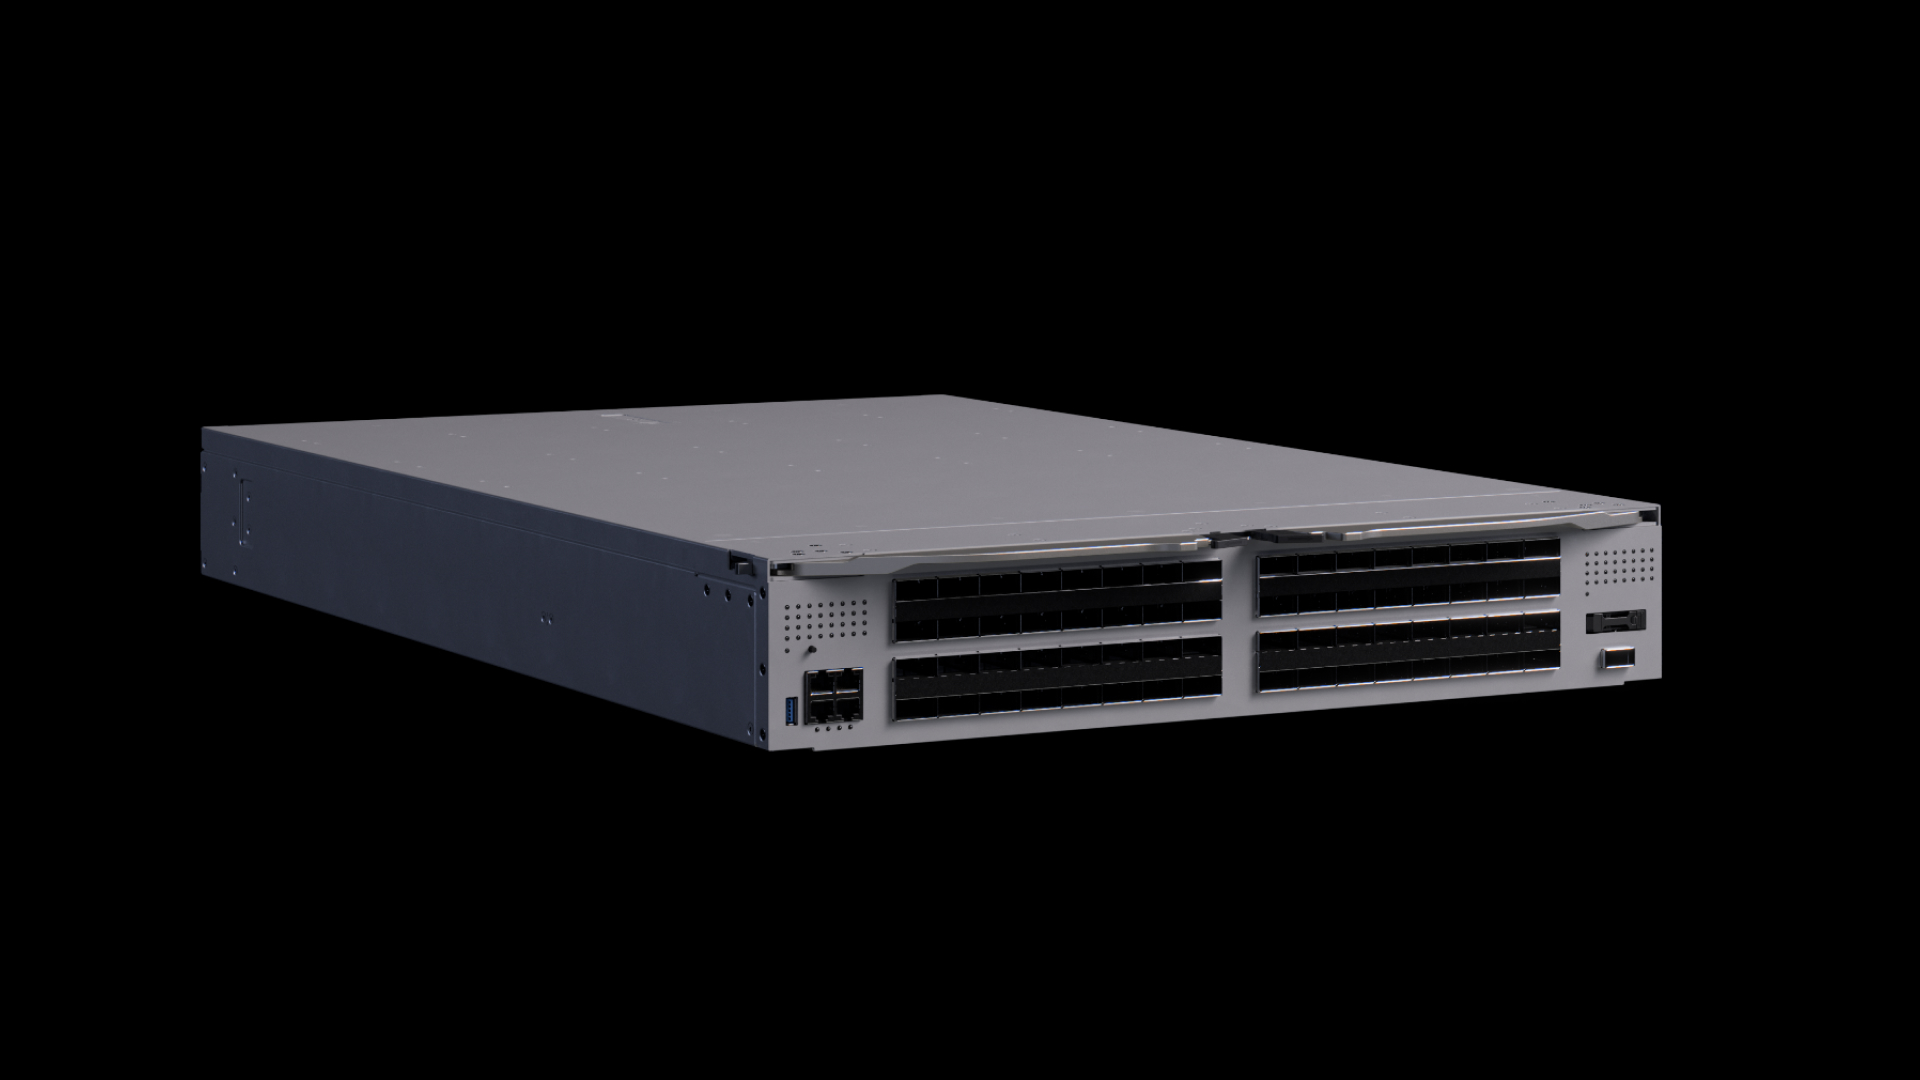
Nvidia is not standing still. At the Open Compute Project Global Summit in San Jose, SiliconANGLE reports the company announced new partnerships and open-source contributions aimed at the foundation for agentic AI infrastructure. Central to those announcements were contributions of Vera Rubin rack and compute tray designs.
This is a strategic response to the same pressure Microsoft is applying. If hyperscalers build their own inference chips, Nvidia's defense is to make its systems the reference architecture for the whole AI factory - racks, trays, networking - and to do so openly enough that operators adopt Nvidia's designs even when they do not buy Nvidia's chips for every layer. Open designs lower integration friction and lock in ecosystem gravity. The AI factory scaling bottlenecks Nvidia is addressing are real, but solving them through open contributions is also a way to keep the industry's physical layer organized around Nvidia's blueprint.
The Stack Is the New Battleground
Taken together, the two stories show the same competitive logic from opposite ends. Microsoft is pulling inference silicon in-house to reduce dependence on Nvidia's GPUs - the Verge reports Maia 300 is designed to be Microsoft's primary AI inference system. Nvidia is pushing outward into rack and networking designs to make its architecture the default for AI factories. Both are fighting over the same territory: where value accrues in the AI hardware stack.
That has direct consequences for US technology companies. Hyperscalers that can design their own inference chips gain a cost advantage in cloud AI services, which pressures margins for those that cannot. Chip designers that only sell discrete accelerators face customers who increasingly want to buy systems, not parts. Networking and interconnect suppliers become more strategically important because they sit between the two. And the open-source route Nvidia is taking means the physical standards for AI data centers may be set in the open, which lowers barriers for new entrants but also freezes in the incumbent's preferred layout.